
GIGABYTE Radeon RX 9070 XT Gaming OC 16G
4.7Editor score
16GB GDDR6 Memory
PCIe 5.0 Support
Affordable Entry Point
This guide compares the top GPUs for running large language models locally, focusing on VRAM capacity, architecture, and inference performance for AI enthusiast
Choosing the right GPU for LLM workloads is essential for developers and researchers who need fast local inference. Modern AI models demand high memory bandwidth and significant VRAM to run efficiently without cloud dependencies.
We evaluated ten professional and consumer graphics cards based on their architecture, memory size, and cooling solutions. Our analysis focuses on real-world usability for AI training, fine-tuning, and deployment in workstation environments.
Each pick highlights specific strengths like memory capacity or power efficiency. Prices and availability change frequently, so verify current listings before purchasing to ensure you get the best value for your specific AI computing needs.
4.7Editor score

3.6Editor score

4.3Editor score
The following comparison table provides a side-by-side look at the technical specifications and key features of each selected graphics card. Use this data to identify which model aligns best with your specific computational requirements and budget constraints.




The ASUS Turbo Radeon AI PRO R9700 stands out as a dedicated solution for running large language models locally. Its 32GB GDDR6 VRAM provides the necessary headroom to load substantial models without offloading to system RAM, which is critical for smooth inference workflows.
We may earn a commission when you buy through this link, at no additional cost to you.
Built on AMD's RDNA 4 architecture with 128 AI Accelerators, this card delivers impressive INT4 TOPS performance for fine-tuning and inference tasks. The wave-pattern diecast shroud effectively cuts memory temperatures by up to 16 percent, ensuring stable clock speeds during extended training sessions.
While the blower-style cooler is ideal for multi-GPU stacking, it can be louder than traditional fans at high loads. The dual ball fan bearings offer durability, but users should ensure their chassis has adequate exhaust airflow to handle the heat dissipation from this professional workstation card.
This GPU is ideal for developers needing a balance of capacity and price. It supports dense multi-GPU builds for local AI clusters, making it a strong recommendation for teams building private inference servers without relying on cloud subscriptions or external data centers.
This card is explicitly designed to run LLMs locally, leveraging the RDNA 4 architecture and AI Accelerators to ensure fast inference times without external dependencies.
The PCIe 5.0 interface and 2-slot design allow for dense stacking in server racks, enabling users to scale their AI performance across multiple cards efficiently.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE Radeon RX 9070 XT offers a compelling entry point for hobbyists and researchers entering the world of local LLM inference. With 16GB of GDDR6 memory, it fits many open-source models comfortably while maintaining a competitive price range for consumer hardware.
We may earn a commission when you buy through this link, at no additional cost to you.
Powered by Radeon RX architecture, this card utilizes server-grade thermal conductive gel to ensure heat transfers efficiently from the GPU core to the heatsink. The WINDFORCE cooling system includes multiple fans to keep the card cool even during sustained computational loads typical of AI tasks.
Although it lacks the specific AI driver optimizations found in professional workstation cards, its raw compute power is sufficient for many inference workloads. The PCIe 5.0 support ensures future-proof bandwidth for data transfer between the CPU and GPU during model loading.
For those on a budget who still require significant VRAM, this card is a top recommendation. It balances cost and performance effectively, making it accessible for individuals who want to experiment with local AI without investing in enterprise-grade hardware immediately.
Sixteen gigabytes of VRAM allows users to run quantized versions of large language models, providing a low-cost entry into private AI hosting.
The use of server-grade thermal gel and multi-fan cooling ensures that the GPU remains stable during long inference sessions or initial fine-tuning processes.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVlDlA RTX PRO 6000 Blackwell max-Q is a powerhouse designed for professionals who cannot compromise on memory capacity or reliability. With 96GB of GDDR7 ECC memory, it can host the largest open-source LLMs locally without any need for system RAM offloading or complex sharding techniques.
We may earn a commission when you buy through this link, at no additional cost to you.
Engineered with the cutting-edge NVIDIA Blackwell architecture, this workstation card delivers up to 3,511 TOPS of AI performance. The 512-bit bus width and 1,792 GB/s memory bandwidth ensure that data movement does not become a bottleneck during complex inference or data science pipelines.
The Max-Q design caps power consumption at 300 Watts while maintaining high performance, which is crucial for thermal management in dense server or desktop environments. Its professional drivers are optimized for stability during long training runs, reducing the risk of errors during critical research phases.
This GPU is ideal for enterprise teams and research labs requiring maximum throughput. If your workflow involves massive datasets or high-concurrency inference requests, this card provides the foundation to scale intelligence rapidly without cloud latency or subscription overhead.
Ninety-six gigabytes of VRAM eliminates bottlenecks, allowing you to run the most advanced models locally with full precision and context windows.
Built for agentic workflows and advanced data science, this card offers the reliability needed for 24/7 operations in professional environments.
We may earn a commission when you buy through this link, at no additional cost to you.
The GIGABYTE RTX 5080 Gaming OC brings the latest Blackwell architecture to the consumer market, offering strong performance for AI tasks. With 16GB of fast GDDR7 memory and a 256-bit interface, it handles many mid-sized LLMs efficiently while providing excellent frame rates for visualization tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
The WINDFORCE cooling system is designed to dissipate heat effectively during heavy computational loads. Integrated with GeForce RTX 5080 technology, this card supports DLSS 4 and advanced AI features, making it versatile for both inference and graphics rendering workloads.
While 16GB of VRAM is standard for high-end gaming cards, it may limit the size of models you can run without quantization. However, for users who need a single card for mixed workloads including gaming and local AI, this card offers a balanced solution.
This GPU is suitable for power users who require speed and reliability. The PCIe 5.0 interface ensures future bandwidth needs are met, making it a solid investment for those planning to upgrade their workstation in the coming years without replacing the primary graphics card.
The new Blackwell architecture improves efficiency and performance, enabling faster AI processing and better thermal management under load.
Beyond AI, this card supports professional rendering and gaming, allowing a single setup to handle diverse creative and computational tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
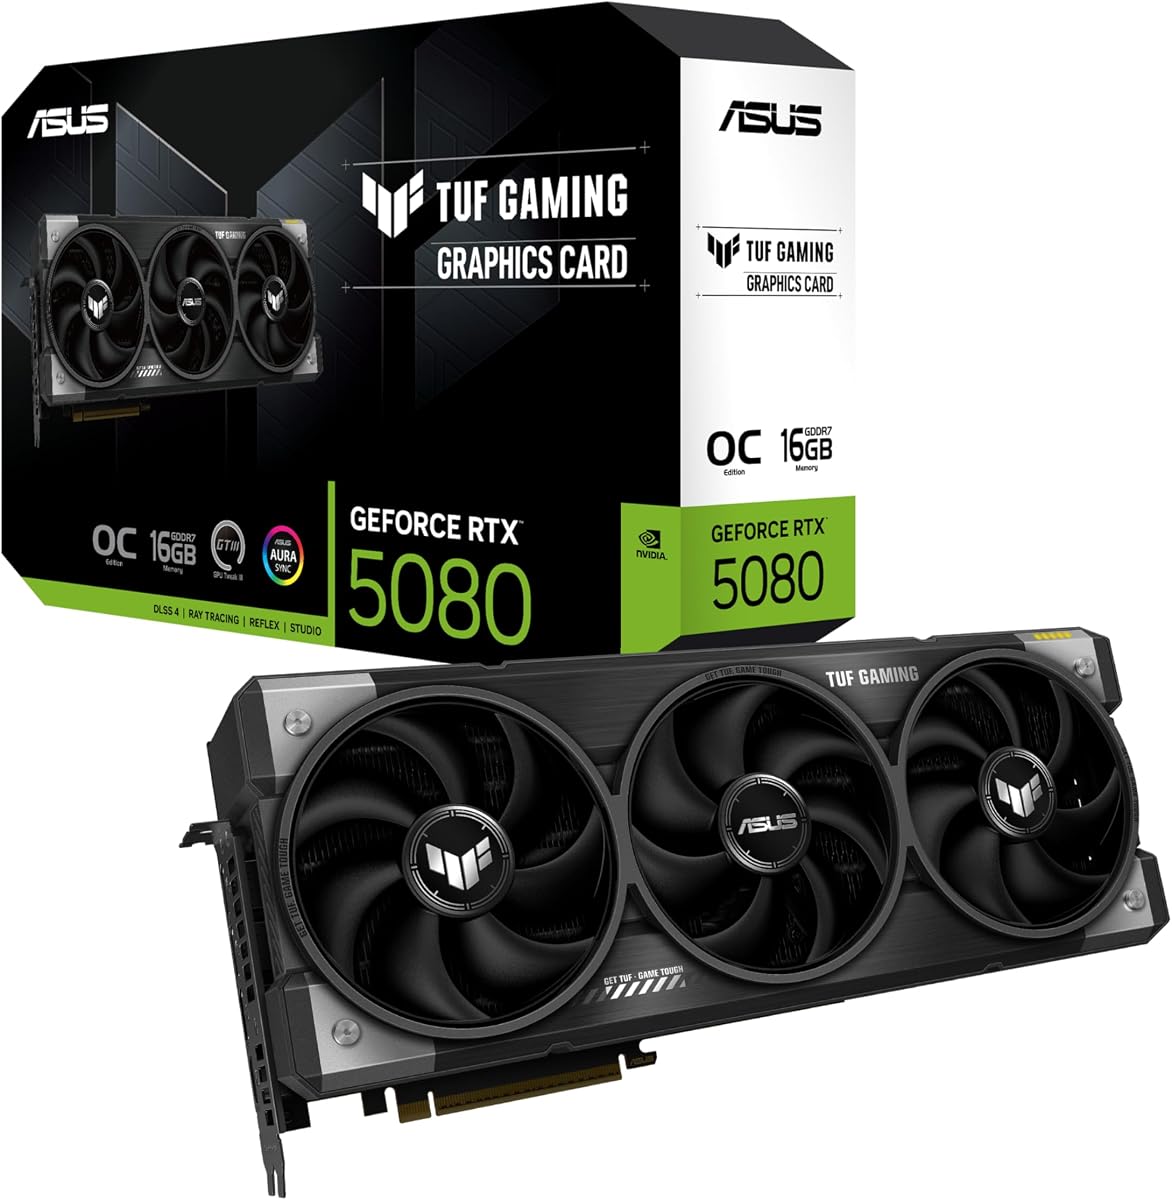
The ASUS TUF Gaming RTX 5080 emphasizes durability and thermal stability for intense workloads. Its 16GB GDDR7 memory combined with a phase-change thermal pad ensures consistent performance during long AI inference sessions by maintaining optimal temperatures over time.
We may earn a commission when you buy through this link, at no additional cost to you.
Military-grade components and protective PCB coating provide extra resilience against dust and moisture. This makes the card well-suited for environments where reliability is critical, such as 24/7 home server setups or small office deployments without dedicated climate control.
The 3.6-slot design accommodates a massive fin array optimized for airflow, though it requires a larger case. Users should confirm case clearance and slot spacing, but the included GPU bracket helps support the weight of this robust card during installation.
This GPU is recommended for users who prioritize hardware longevity. The combination of phase-change pads and auto-extreme precision manufacturing means the card is built to last, reducing the risk of thermal throttling or failure during critical development cycles.
Phase-change thermal pads outlast traditional paste, ensuring thermal performance remains stable over years of heavy GPU usage.
Military-grade components and PCB coating add layers of protection that extend the card's lifespan in challenging operational environments.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Arc Pro B60 Creator is uniquely equipped for multi-monitor AI workflows. Its 24GB GDDR6 memory offers substantial capacity for running models while managing multiple high-resolution displays via four DP 2.1 outputs, which is rare in this category.
We may earn a commission when you buy through this link, at no additional cost to you.
Built on Intel's Xe2-HPG architecture with 20 Xe cores and 160 XMX engines, it provides decent AI acceleration. The card is optimized for Linux multi-GPU deployments, allowing users to scale performance across multiple units for a distributed inference cluster.
The blower-style cooling helps expel heat directly out of the chassis, which is useful for tight server racks. However, users must verify chassis clearance and PSU capacity, as the card requires a single 8-pin power connector and a 200W TDP rating.
This GPU is ideal for teams needing display flexibility and scaling options. If you need to connect several screens for monitoring dashboards while running LLMs locally, this card provides the I/O and memory balance to support that specific workflow effectively.
Four DP 2.1 outputs allow connection to up to four 8K displays, creating expansive workspaces for AI development and monitoring.
Optimized for Linux multi-GPU deployments, enabling scalable AI performance across multiple cards for larger local clusters.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASRock Radeon AI PRO R9700 Creator is engineered for professional AI development and compute-intensive workloads. With 32GB of GDDR6 memory on a 256-bit bus, it provides ample bandwidth for large models, video editing, and complex 3D rendering tasks.
We may earn a commission when you buy through this link, at no additional cost to you.
AMD RDNA 4 features 64 Compute Units with dedicated AI Accelerators for groundbreaking performance. The enterprise-grade thermal solution uses a vapor chamber heatsink with Honeywell PTM7950 material, ensuring reliable cooling under sustained professional loads in studio environments.
This card is ISV certified for AI, design, engineering software, ensuring stability with professional drivers. The standard 2-slot design maximizes density in server racks, making it suitable for building compact multi-GPU workstation servers for enterprise or research labs.
This GPU is recommended for professionals needing reliable, certified hardware. If your work involves critical design or engineering alongside AI models, the robust build quality and optimized drivers provide the stability required for 24/7 operation.
ISV certification ensures validated support for professional applications, reducing compatibility issues in mixed workload environments.
The vapor chamber and industrial thermal interface material maintain consistent performance during long sessions without overheating.
We may earn a commission when you buy through this link, at no additional cost to you.
The ASUS Dual RTX 5060 Ti brings 16GB of GDDR7 memory into a compact 2.5-slot design. This makes it perfect for small form factor builds where space is limited but AI inference capabilities are still required for local testing or lightweight models.
We may earn a commission when you buy through this link, at no additional cost to you.
Powered by the NVIDIA Blackwell architecture, it delivers strong performance per watt. The Axial-tech fan design features a smaller hub for longer blades, increasing downward air pressure to cool the GPU efficiently even in cramped cases.
Dual BIOS allows toggling between Quiet and Performance profiles, while 0dB technology ensures silence during light loads. Dual ball fan bearings offer increased durability, lasting up to twice as long as conventional sleeve bearing designs for better long-term reliability.
This GPU is ideal for developers with limited desk space. Despite its size, the memory capacity allows for running smaller LLMs locally, and the dual BIOS ensures you can prioritize silence when not actively training models or running inference tasks.
The 2.5-slot design maximizes compatibility with small chassis while maintaining cooling efficiency through optimized fan geometry.
Dual BIOS lets you choose between Quiet and Performance modes, tailoring the card to your specific noise tolerance needs.
We may earn a commission when you buy through this link, at no additional cost to you.
The Tesla L40S is a specialized graphics accelerator designed for data centers and heavy HPC workloads. With 48GB of VRAM, it can host larger models than standard consumer cards, making it suitable for production inference environments where capacity is key.
We may earn a commission when you buy through this link, at no additional cost to you.
This card is built for enterprise AI deployment and supports professional workflows. While it often lacks display outputs, its compute power is optimized for headless server environments where multiple units are installed to form a powerful inference or training cluster.
The robust construction ensures stability in high-density racks. It supports professional software stacks and is engineered to run complex deep learning tasks without the thermal constraints of consumer-grade hardware.
This GPU is recommended for organizations building private AI infrastructure. If you need a card specifically for high-memory AI tasks in a server rack, the L40S provides the reliability and capacity to handle demanding HPC requirements.
Forty-eight gigabytes of memory allows for running large models without needing complex offloading strategies or sharding.
Designed for HPC environments, this card supports stable operation in data center racks with professional support ecosystems.
We may earn a commission when you buy through this link, at no additional cost to you.
The NVD RTX PRO 6000 Blackwell OEM edition delivers massive performance for enterprise-grade AI workloads. With 96GB of DDR7 ECC memory, it supports the largest LLMs and complex simulations without external storage or system RAM dependencies.
We may earn a commission when you buy through this link, at no additional cost to you.
Featuring the Double-Flow-Through Design, cooling is optimized for peak performance under 600W power loads. The 5th Gen Tensor Cores support FP4 precision, enabling local fine-tuning of LLMs with reduced memory usage and faster processing times.
Universal MIG allows you to divide the GPU into multiple isolated instances. This lets concurrent workloads run securely and efficiently, maximizing utilization across different users or applications within the same physical card.
This GPU is ideal for large teams needing GPU partitioning. If you require secure isolation of different applications while maximizing hardware usage, the MIG feature on this card provides the flexibility to share resources efficiently.
Divide the GPU into isolated instances to allow concurrent execution of multiple workloads with secure resource allocation.
Double-Flow cooling ensures peak performance under heavy loads by optimizing efficiency and airflow through the card.
We may earn a commission when you buy through this link, at no additional cost to you.
Selecting the right GPU for LLM workloads requires balancing memory capacity, architecture, and physical constraints. This guide outlines key factors to help you find a card that fits your specific computing environment.
The amount of Video Random Access Memory determines how large a model you can load locally. For efficient inference and fine-tuning, look for cards with at least 16GB of VRAM, though 32GB or more is preferred for larger models without quantization.
Prioritize higher VRAM capacity to avoid reliance on system RAM, which significantly slows down inference speeds.
Bandwidth affects how fast data moves between the GPU memory and processor. Look for cards with DDR7 or GDDR6 with high bandwidth to ensure smooth data transfer during complex model operations.
Higher bandwidth ensures faster response times when loading and running models in real-world scenarios.
Modern architectures like Blackwell or RDNA 4 include dedicated AI accelerators or tensor cores that speed up inference tasks. Check if the card supports FP4 or INT4 precision for faster processing.
Choose a card with dedicated AI engines to maximize speed for specific language model tasks.
Workstation GPUs often use blower coolers and multi-slot designs to fit into server racks. Verify your case clearance and slot spacing to ensure the card fits properly without obstruction.
Measure your chassis before purchasing to avoid compatibility issues with larger workstation cards.
High-performance cards require significant power. Check the TDP and power connector requirements, such as 12VHPWR or 8-pin connectors, and ensure your PSU can handle the load.
Verify your PSU capacity and connectors to prevent system instability during high-load tasks.
Ensure the card is compatible with your operating system, especially if using Linux for multi-GPU scaling. Professional drivers are often required for stable AI workloads on enterprise cards.
Check software compatibility lists to ensure driver support for your specific OS and frameworks.
If you plan to run a cluster, look for cards optimized for Linux multi-GPU support. This allows you to combine multiple GPUs to increase total VRAM and compute power.
Select cards explicitly mentioning multi-GPU scaling if you plan to expand your cluster later.
Sustained workloads generate heat. Blower fans help expel heat from tight server spaces, while axial fans offer better airflow for open cases. Choose based on your enclosure type.
Select a cooling style that matches your case airflow to prevent thermal throttling during long runs.
Start by ensuring your motherboard and power supply can handle the new card. Install the latest drivers from the manufacturer to enable all AI features and stability patches.
Keep the card clean and monitor temperatures using system software. Dust buildup can degrade thermal performance, so clean the fans regularly with compressed air.
For multi-GPU setups, configure the software to distribute workloads evenly across cards. Use tools that support PCIe 5.0 bandwidth to maximize data transfer speeds.
For basic chat models, 16GB is often sufficient. For larger models with longer context windows, aim for 32GB or more. High-end workstation cards with 96GB allow running the largest models without offloading.
NVIDIA cards dominate due to CUDA support, but AMD and Intel also offer models with AI accelerators. Choose based on software compatibility and ecosystem support for your specific tools.
Yes, many gaming cards like the RTX 5080 handle inference well. However, professional cards offer better stability and memory ECC features for 24/7 operation.
PCIe 5.0 offers double the bandwidth of PCIe 4.0, which speeds up data transfer between CPU and GPU. This is beneficial when loading large models into VRAM quickly.
Professional cards often include ECC memory, better cooling, and enterprise drivers. These features provide reliability for long training runs and complex data science workflows.
Yes, multi-GPU setups allow pooling VRAM. Ensure your card supports this feature and your software configuration supports distributed workloads across devices.
We highlighted top picks across budget, mid-range, and premium categories to suit various needs. Whether you need 16GB for entry-level tasks or 96GB for enterprise workloads, there is a card that fits your workflow.
Prioritize memory capacity and architecture compatibility when making your choice. A card with sufficient VRAM and AI accelerators will future-proof your investment against growing model sizes.
Remember to verify current stock and specifications before purchasing. Prices and availability change rapidly, so checking the latest listings ensures you get the best option for your computing setup.